Education Hub for Generative AI

Tag: parallel decoding

Parallel Transformer Decoding Strategies for Low-Latency LLM Responses 31 January 2026

Parallel Transformer Decoding Strategies for Low-Latency LLM Responses

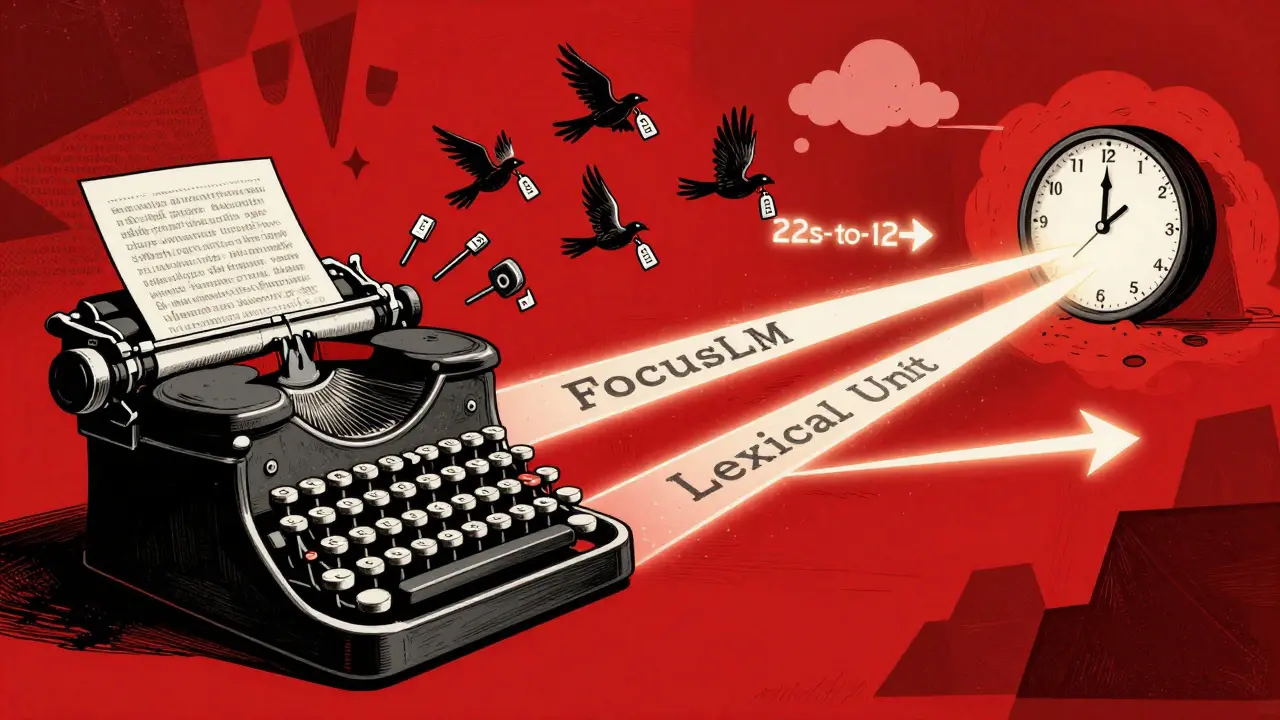
Parallel decoding cuts LLM response times by up to 50% by generating multiple tokens at once. Learn how Skeleton-of-Thought, FocusLLM, and lexical unit methods work-and which one to use for your use case.
Susannah Greenwood 6 Comments

About

AI & Machine Learning

Latest Stories

CCPA Compliance for Vibe-Coded Web Apps: How to Handle Do Not Sell and User Requests

CCPA Compliance for Vibe-Coded Web Apps: How to Handle Do Not Sell and User Requests

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

Token-Level Logging Minimization: Protecting Privacy in LLM Systems

Token-Level Logging Minimization: Protecting Privacy in LLM Systems

Prompting for Docs: How to Generate READMEs, ADRs, and Code Comments with AI

Prompting for Docs: How to Generate READMEs, ADRs, and Code Comments with AI

Privacy-Aware RAG: Stop Sensitive Data Leaks in LLMs

Privacy-Aware RAG: Stop Sensitive Data Leaks in LLMs

Temperature Tuning for LLMs: Balancing Creativity and Precision

Temperature Tuning for LLMs: Balancing Creativity and Precision

Vibe Coding Productivity: The Truth Behind the 74% Uplift Myth

Vibe Coding Productivity: The Truth Behind the 74% Uplift Myth

Education Hub for Generative AI
© 2026. All rights reserved.