Evaluating Factuality in LLMs: Grounded Generation and Fact-Checking Pipelines
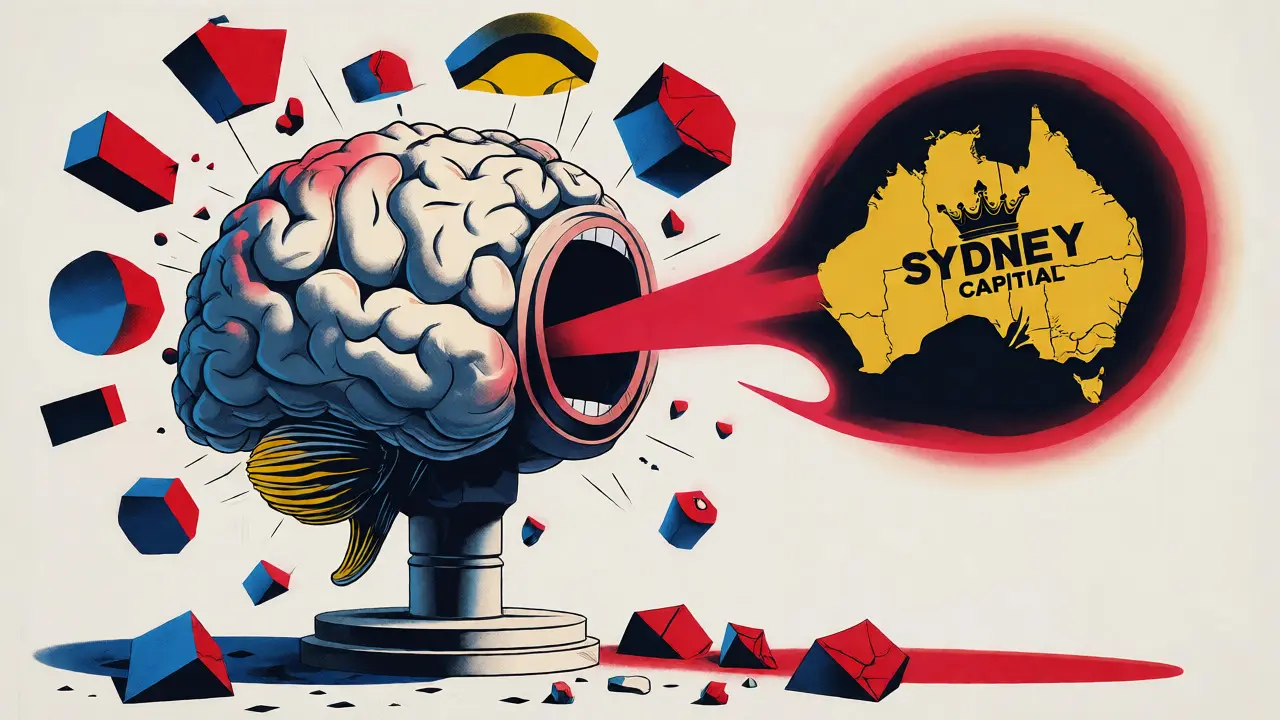
You ask an AI for the capital of Australia. It confidently says Sydney. You know it's Canberra. This isn't just a mistake; it's a hallucination. In 2026, as Large Language Models (LLMs) handle everything from medical summaries to legal drafts, this problem is no longer a quirky bug-it’s a critical failure point. If your model can’t tell truth from fiction, it can’t be trusted in production.
Evaluating factuality isn’t about checking if the grammar is perfect. It’s about verifying that every claim made by the model is grounded in reality or provided context. This guide breaks down how modern teams assess factual accuracy using grounded generation techniques and robust fact-checking pipelines. We’ll look at the metrics that matter, the tools you need, and how to build a system that catches errors before they reach your users.
Why Traditional Metrics Fail on Facts
For years, developers relied on metrics like Perplexity or BLEU scores to judge model quality. These measure how well a model predicts the next word or matches reference translations. They are great for fluency but terrible for truth. A model can generate a grammatically perfect sentence that is completely false. That’s why we need specific factuality metrics.
Consider Exact Match (EM). It checks if the output perfectly matches a reference answer. While useful for simple Q&A, it’s too rigid for complex tasks. If a model says "The Earth orbits the Sun" versus "The Sun is orbited by the Earth," EM might fail one while both are true. Instead, we look at Precision and Recall. Precision tells you what percentage of the facts generated are correct. Recall tells you how many of the necessary facts were actually included. The F1 Score balances these two, giving you a single number that reflects both accuracy and coverage.
But numbers alone aren’t enough. You need fine-grained analysis. This is where atomic fact decomposition comes in. Tools like FACTSCORE break down long-form text into individual, verifiable statements. For example, a biography paragraph becomes ten separate claims. Each claim is then checked against a knowledge base like Wikipedia. This approach reveals exactly where the model starts drifting from the truth, rather than just telling you the whole paragraph was "mostly right."
The Role of Grounded Generation
If you want fewer hallucinations, stop letting the model rely solely on its internal memory. Internal knowledge is static and often outdated. Grounded generation forces the model to use external information as the source of truth. The most common implementation today is Retrieval-Augmented Generation (RAG).
In a RAG pipeline, the user’s query triggers a search in a vector database. Relevant documents are retrieved and injected into the prompt. The model then generates an answer based *only* on those documents. This shifts the burden of factuality from the model’s weights to the retrieval system. If the retrieval finds the right document, the model has a much better chance of being accurate.
However, RAG introduces new failure modes. The model might ignore the retrieved context and stick to its pre-trained bias. Or, it might misinterpret the retrieved text. To evaluate this, you need specific metrics beyond standard accuracy:
- Faithfulness: Does the answer contain only information found in the retrieved context?
- Context Relevance: Did the retrieval step actually find helpful documents?
- Answer Relevance: Is the final answer directly addressing the user’s question?
Tools like LangChain Evaluation Toolkit provide built-in checks for these RAG-specific issues. Without them, you’re flying blind. You might think your model is smart, when in reality, your retrieval step is just failing to find the right data.
Building a Fact-Checking Pipeline
A robust fact-checking pipeline doesn’t just run once; it operates continuously during development and deployment. Here is how mature teams structure their evaluation stack in 2026.
| Approach | Best Use Case | Pros | Cons |
|---|---|---|---|
| Atomic Fact Decomposition (FACTSCORE) | Long-form content, biographies, news summaries | High granularity, identifies specific false claims | Computationally expensive, requires reliable KB |
| SelfCheckGPT (Sampling) | Zero-resource settings, open-ended queries | No ground truth needed, detects inconsistency | Slower (requires multiple samples), assumes consistency equals truth |
| LLM-as-a-Judge | Subjective quality, tone, general coherence | Scalable, flexible criteria | Judge model may itself hallucinate, biased preferences |
| Human-in-the-Loop | Critical applications (medical, legal) | Highest accuracy, nuanced understanding | Expensive, slow, not scalable for real-time |
Most production systems combine these methods. You start with automated checks like SelfCheckGPT to flag potential inconsistencies. Then, you route flagged outputs to a secondary verification step-either another LLM acting as a judge or a human reviewer for high-stakes cases.
OpenFactCheck is a notable framework here. It allows you to customize checkers for specific domains. If you’re building a finance bot, you can plug in a checker that verifies numerical data against live market APIs. If you’re doing healthcare, you link it to PubMed abstracts. This modularity is key because "factuality" means different things in different industries.
Detecting Hallucinations Without Ground Truth
Sometimes, you don’t have a clean dataset to compare against. Maybe you’re generating creative non-fiction or synthesizing recent news. How do you check facts when there’s no single "right" answer? Enter self-consistency methods like SelfCheckGPT.
The logic is simple: if a model truly knows a fact, it will state it consistently across multiple generations. If it’s hallucinating, the details will drift between samples. By generating five variations of the same answer and comparing them, you can calculate a consistency score. Low consistency suggests the model is making things up. This is particularly powerful for evaluating closed-source models where you don’t have access to internal logits.
Another technique is citation checking. Force the model to cite sources for every claim. Then, programmatically verify if those citations exist and support the statement. If the model cites "Study X, 2023" but Study X doesn’t mention that topic, you’ve caught a fabrication. This works best when paired with strict prompting instructions that forbid the model from inventing references.
Mitigation Strategies Beyond Evaluation
Evaluation tells you if you have a problem. Mitigation fixes it. You can’t just hope the model gets better over time. You need active strategies.
First, improve your training data. Supervised fine-tuning on curated datasets-like peer-reviewed journals or verified encyclopedias-teaches the model to prioritize accurate phrasing. But data quality matters more than quantity. A small, high-quality dataset beats a massive, noisy web scrape every time.
Second, optimize your prompts. Chain-of-thought reasoning helps significantly. Ask the model to "think step-by-step" before answering. This forces it to retrieve relevant facts logically rather than guessing the next token. Adding explicit constraints like "If you are unsure, say 'I don't know'" also reduces confident nonsense.
Third, implement retrieval filters. Don’t just dump all retrieved chunks into the prompt. Use rerankers to filter out irrelevant noise. If the context is clean, the model is less likely to get confused. Deepchecks and similar tools offer automated regression testing that alerts you when a prompt change causes a drop in groundedness scores.
Choosing the Right Tool for Your Stack
The 2026 landscape offers several specialized platforms. Choosing the right one depends on your scale and complexity.
- LangSmith & Braintrust: Best for developers who need deep observability into traces and spans. Great for debugging RAG chains.
- Deepchecks: Ideal for automated CI/CD integration. It runs comprehensive suites of tests including bias, robustness, and factuality checks automatically.
- Vellum & Confident AI: Good for teams wanting a unified interface for evaluation and experimentation without heavy coding overhead.
Don’t fall into the trap of using just one metric. A high F1 score on a benchmark doesn’t mean your chatbot won’t lie to a customer. Always pair automated metrics with qualitative review. Sample 5% of your traffic manually each week. Look for patterns in the failures. Are they date-related? Entity confusion? Numerical errors? These insights drive targeted improvements better than any dashboard.
What is the difference between precision and recall in factuality evaluation?
Precision measures the proportion of generated facts that are correct (minimizing false positives/hallucinations). Recall measures the proportion of all possible correct facts that the model successfully included (minimizing false negatives/omissions). High precision means few lies; high recall means complete answers. The F1 score balances both.
How does FACTSCORE work?
FACTSCORE decomposes generated text into atomic, indivisible facts. It then verifies each atomic fact against a trusted knowledge base (like Wikipedia). The final score is the percentage of atomic facts that are supported by the knowledge base. This provides fine-grained insight into exactly which parts of a long response are inaccurate.
Can I evaluate factuality without ground truth data?
Yes. Methods like SelfCheckGPT use sampling-based approaches. By generating multiple responses to the same prompt, the system checks for consistency. If the model varies significantly between samples, it indicates uncertainty or hallucination. Additionally, LLM-as-a-judge can assess plausibility and logical coherence even without a strict reference answer.
Why is RAG evaluation different from standard LLM evaluation?
RAG involves two stages: retrieval and generation. Standard evaluation only looks at the final text. RAG evaluation must separately measure Context Relevance (did we retrieve good docs?), Faithfulness (did the model use the docs?), and Answer Relevance (does it answer the question?). Failure in retrieval cannot be fixed by better generation, so isolated metrics are crucial.
Is human review still necessary in 2026?
For high-stakes applications (legal, medical, financial), yes. Automated tools catch obvious errors and inconsistencies, but humans are needed to detect subtle nuances, sarcasm, or domain-specific inaccuracies that automated checkers miss. Human-in-the-loop systems also provide feedback data to retrain and fine-tune models over time.