Education Hub for Generative AI

Tag: FP16

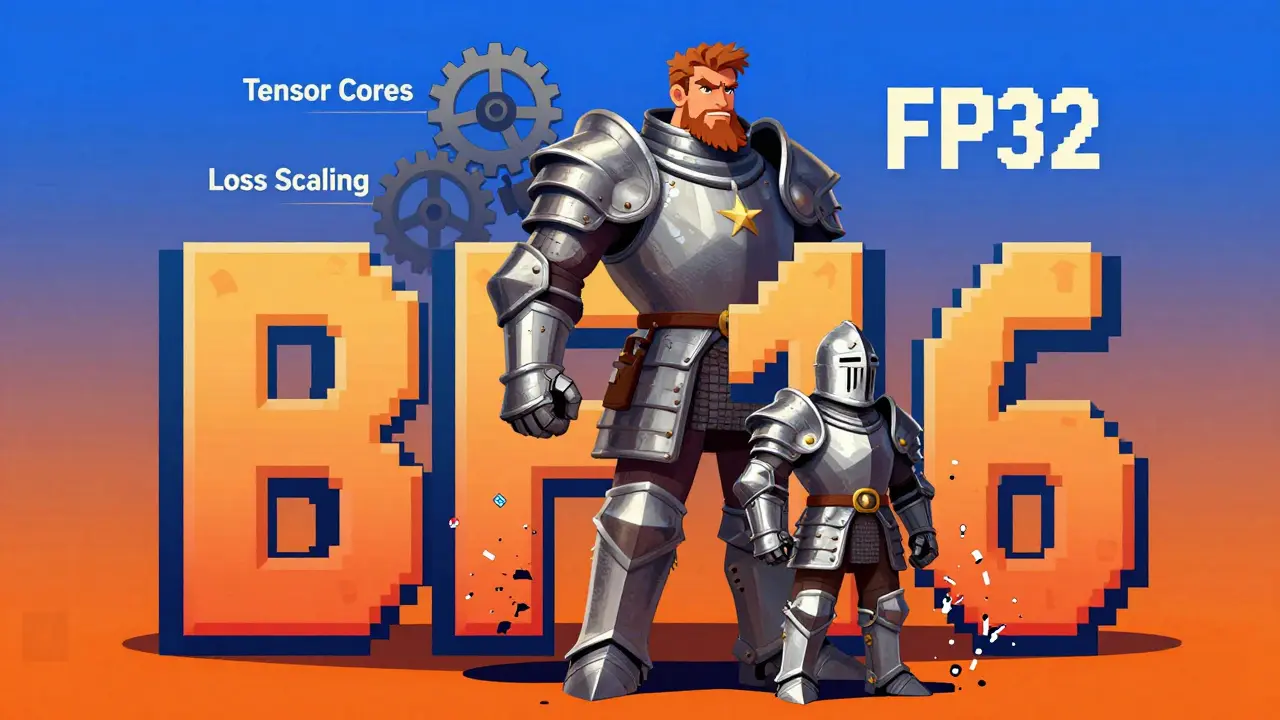
Mixed-Precision Training for Large Language Models: FP16, BF16, and Beyond 16 December 2025

Mixed-Precision Training for Large Language Models: FP16, BF16, and Beyond

Mixed-precision training using FP16 and BF16 cuts LLM training time by up to 70% and reduces memory use by half. Learn how it works, why BF16 is now preferred over FP16, and how to implement it safely with PyTorch.
Susannah Greenwood 8 Comments

About

AI & Machine Learning

Latest Stories

Role Assignment in Vibe Coding: How Senior Architect and Junior Developer Prompts Change Code Output

Role Assignment in Vibe Coding: How Senior Architect and Junior Developer Prompts Change Code Output

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

Anonymization vs Pseudonymization in LLM Workflows: A Practical Guide

Anonymization vs Pseudonymization in LLM Workflows: A Practical Guide

Vibe Coding Tools Cost Comparison for Startups in 2026

Vibe Coding Tools Cost Comparison for Startups in 2026

Token-Level Logging Minimization: Protecting Privacy in LLM Systems

Token-Level Logging Minimization: Protecting Privacy in LLM Systems

Task-Specific Scorecards: Evaluating LLM Summarization, Q&A, and Extraction

Task-Specific Scorecards: Evaluating LLM Summarization, Q&A, and Extraction

Vibe Coding Productivity: The Truth Behind the 74% Uplift Myth

Vibe Coding Productivity: The Truth Behind the 74% Uplift Myth

Education Hub for Generative AI
© 2026. All rights reserved.