Education Hub for Generative AI

Tag: multimodal transformers

Multimodal Transformer Foundations: How Text, Image, Audio, and Video Embeddings Are Aligned 30 November 2025

Multimodal Transformer Foundations: How Text, Image, Audio, and Video Embeddings Are Aligned

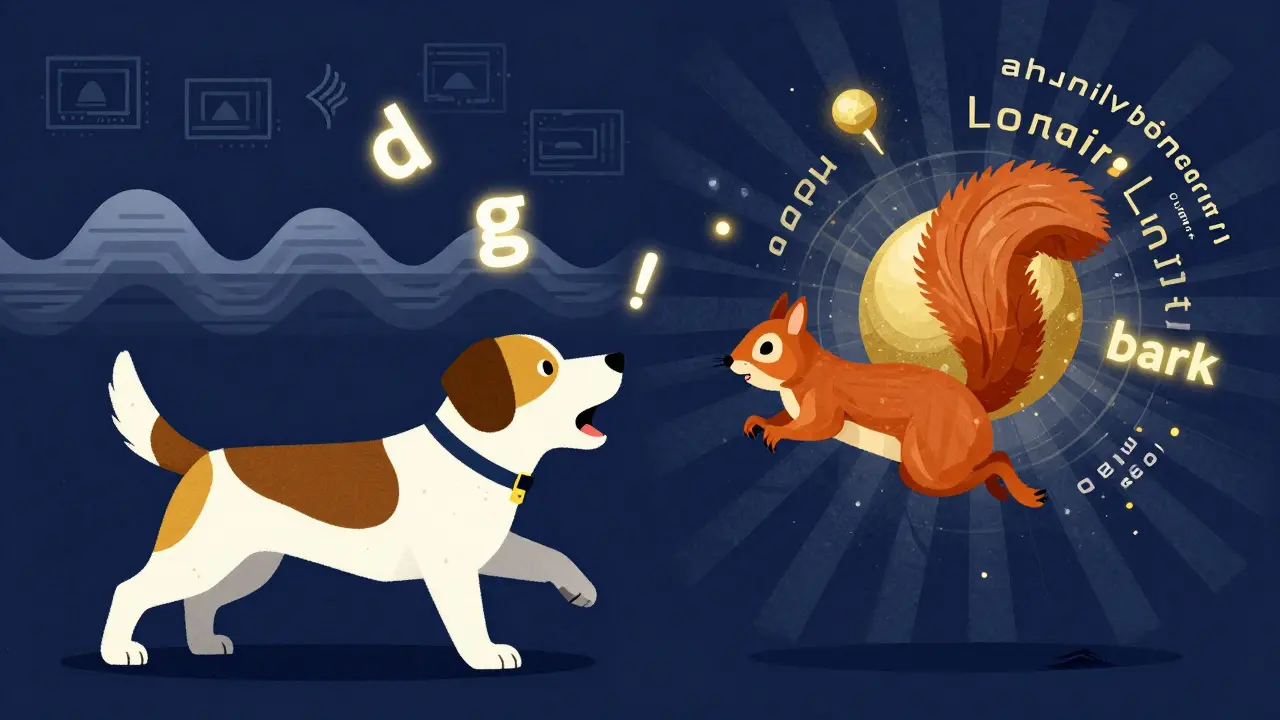
Multimodal transformers align text, image, audio, and video into a shared embedding space, enabling systems to understand the world like humans do. Learn how they work, where they're used, and why audio remains the hardest modality to master.
Susannah Greenwood 7 Comments

About

AI & Machine Learning

Latest Stories

How to Capture Project Style Guides in System Prompts for Consistency

How to Capture Project Style Guides in System Prompts for Consistency

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

Generative AI Cost Models: Build vs Buy, Token Pricing, and Infrastructure Guide

Generative AI Cost Models: Build vs Buy, Token Pricing, and Infrastructure Guide

Operating Model for LLM Adoption: Teams, Roles, and Responsibilities

Operating Model for LLM Adoption: Teams, Roles, and Responsibilities

Domain Adaptation for LLMs: Medical, Legal, and Finance Examples

Domain Adaptation for LLMs: Medical, Legal, and Finance Examples

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Keeping RAG Systems Fresh: Document Sync Strategies for LLMs

Keeping RAG Systems Fresh: Document Sync Strategies for LLMs

Education Hub for Generative AI
© 2026. All rights reserved.