Building Custom LLM Benchmarks for Enterprise Success
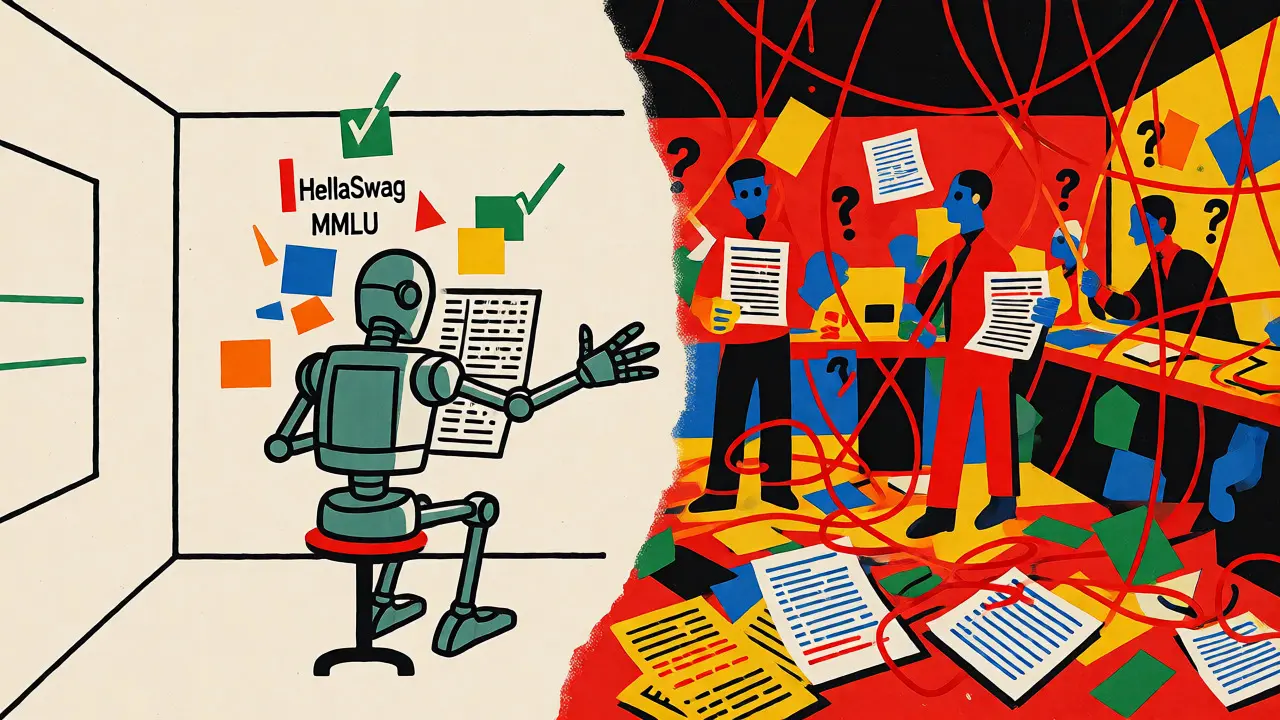
You’ve just deployed a state-of-the-art Large Language Model (LLM) into your customer support workflow. On paper, it scores high on HellaSwag and general reasoning benchmarks. But in production, it hallucinates product names, misses compliance nuances, and fails to retrieve the correct internal policy document. Sound familiar? This is the classic trap of relying on generic academic benchmarks for enterprise applications. The gap between "passing a test" and "solving a business problem" is where most enterprise AI projects stall.
Standard benchmarks like ARC or MMLU measure general knowledge-things like "Which factor causes fever?" Your business doesn’t care about fevers; it cares about locating conference rooms, processing software tickets, or drafting legally compliant emails. To bridge this gap, you need custom benchmarks tailored specifically to your organizational context. Here is how to build them effectively, ensuring your LLM delivers real value rather than just good test scores.
Why Generic Benchmarks Fail in Enterprise Contexts
Most public datasets are designed for broad applicability, not specific utility. They assume static inputs and controlled environments. In contrast, enterprise environments are dynamic, messy, and heavily regulated. A model might ace a coding challenge but fail miserably at summarizing a complex contract because it lacks domain-specific grounding. Research from Moveworks highlights that traditional benchmarks often miss critical dimensions like regulatory compliance, brand voice adherence, and retrieval accuracy.
When you rely solely on these generic metrics, you risk selecting a model that looks powerful in isolation but performs poorly when integrated with your proprietary data. For instance, a model might generate fluent text but fail to cite the correct internal source, leading to trust issues among employees. Custom benchmarks force you to evaluate what actually matters: can the model solve your problems, consistently and safely?
Defining Your Evaluation Criteria
Before writing a single line of code, define what "success" looks like for your use case. This isn’t just about accuracy; it’s about multi-dimensional performance. You need to assess generation quality, reasoning capability, relevance, extraction precision, and classification reliability. Start by identifying five core themes relevant to your operations, such as:
- Factuality: Does the output align with verified enterprise data?
- Compliance: Does the response adhere to legal and regulatory standards?
- Tone: Does it match your brand voice (e.g., professional, empathetic)?
- Retrieval: Did it pull the right documents using Retrieval-Augmented Generation (RAG)?
- Efficiency: Can it handle long-context inputs without losing coherence?
Collaborate with domain experts-lawyers, support leads, HR managers-to create scoring rubrics. These stakeholders know the edge cases that break standard models. Their input ensures your benchmark reflects real-world behavior, not just theoretical perfection.
Constructing the Dataset: From Data to Trios
Data is the backbone of any custom benchmark. Avoid synthetic examples if possible; use anonymized real-world interactions. The Moveworks team developed a robust approach using "instruction-input-output trios." This format standardizes how you present tasks to the model and how you expect it to respond. For example:
- Instruction: "Summarize this support ticket and suggest a resolution based on Policy X."
- Input: The actual ticket text plus the relevant policy excerpt.
- Output: The ideal summary and resolution drafted by a human expert.
Aim for 200 to 1,000 high-quality examples initially. Include corner cases-ambiguous queries, conflicting information, or extremely long documents. Label Studio research suggests that capturing end-user feedback directly into these test cases helps identify failure points early. Remember to blind-test your dataset; don’t let the same people who wrote the questions also grade the answers during initial validation to avoid bias.
Implementing LLM-as-a-Judge and Human Review
Automated metrics like BLEU or ROUGE are useful for translation but poor for evaluating conversational AI. They ignore tone, nuance, and factual correctness. Instead, adopt an LLM-as-a-Judge methodology. Use a separate, highly capable model (like GPT-4o or Claude 3.5 Sonnet) to score outputs against your defined criteria. Provide the judge with clear instructions: "Rate the helpfulness from 1-5," or "Check if all cited sources are accurate."
However, don’t rely entirely on AI judges. Periodic human review is essential to calibrate the automated scores. Humans catch subtle errors that models miss, such as inappropriate tone or missed compliance flags. This hybrid approach scales better than pure manual review while maintaining higher fidelity than pure automation. Galileo’s framework recommends integrating these custom metrics into continuous monitoring pipelines, so you can detect drift as soon as it happens.
Evaluating Technical Fit: RAG and Fine-Tuning
Your benchmark shouldn’t just test the model; it should test the entire system architecture. Evaluate how well the LLM integrates with your RAG pipeline. Can it correctly interpret retrieved chunks? Does it suffer from "lost in the middle" phenomena when processing long contexts? Test different chunk sizes and retrieval strategies within your benchmark suite.
Additionally, consider the cost-performance trade-off of fine-tuning. Moveworks found that smaller models fine-tuned on enterprise-specific data can outperform larger general-purpose models in specialized tasks. Your benchmark should compare base models against fine-tuned variants. If a 7B parameter model tuned on your data matches the performance of a 70B model on your specific tasks, you’ve saved significant computational costs. Include metrics for inference speed and token usage in your evaluation table.
| Metric Type | Example Metrics | Best For | Limitations |
|---|---|---|---|
| Automated NLP | BLEU, ROUGE, F1 Score | Translation, Summarization, Classification | Ignores semantics, tone, and factuality |
| LLM-as-a-Judge | Helpfulness, Safety, Coherence | Chatbots, Creative Writing, Complex Reasoning | Costly, requires calibration, potential bias |
| Human Review | Expert Scoring, User Satisfaction | Critical Compliance, Brand Voice, High-Stakes Decisions | Slow, expensive, subjective |
| System-Level | Latency, Token Cost, RAG Accuracy | Production Viability, Cost Optimization | Doesn't measure content quality directly |
Continuous Monitoring and Iteration
Benchmarks aren’t set-and-forget artifacts. Business requirements change, new regulations emerge, and user behaviors evolve. Implement a feedback loop where production failures automatically become new benchmark test cases. If a user thumbs-down a response, analyze why. Was it a retrieval error? A reasoning flaw? Add this scenario to your regression suite.
Use red-teaming techniques to stress-test your model. Introduce adversarial prompts designed to trigger hallucinations or compliance breaches. CloudHew emphasizes governance as a critical pillar; your benchmark must verify that the model remains secure and compliant under pressure. Schedule regular re-evaluations whenever you update your model version or change your RAG index. This ensures your AI system stays aligned with organizational goals over time.
How many examples do I need for a custom LLM benchmark?
Start with 200-500 high-quality, diverse examples covering your core use cases. As you scale, aim for 1,000+ to capture edge cases and ensure statistical significance. Quality matters more than quantity; one well-crafted corner case is worth ten easy questions.
Can I use existing public datasets for enterprise benchmarking?
You can use them as a baseline, but they are insufficient alone. Public datasets lack your proprietary terminology, internal policies, and specific business logic. Always augment them with internal, anonymized data reflecting real user interactions.
What is the best way to score subjective qualities like tone?
Use LLM-as-a-Judge with detailed rubrics defining what "professional" or "empathetic" means in your context. Validate these scores with periodic human audits to ensure the AI judge aligns with human expectations.
How does RAG affect my benchmarking strategy?
RAG adds a retrieval layer that can introduce errors independent of the LLM. Your benchmark must separately evaluate retrieval accuracy (did it find the right doc?) and generation quality (did it answer correctly based on that doc?).
Should I fine-tune before or after creating benchmarks?
Create benchmarks first. You need a reliable measuring stick to determine if fine-tuning actually improves performance. Without a custom benchmark, you won’t know if your fine-tuned model is truly better for your specific tasks.