NLP Evaluation: Why BLEU Fails and LLM-as-a-Judge Wins
Imagine you ask an AI to summarize a news article. It gives you a perfect summary, but it uses different words than the original headline. A traditional metric like BLEU might give it a terrible score because it doesn't see the exact same words. That sounds broken, right? Yet for twenty years, this was how we judged AI. Today, that's changing fast. We are moving from rigid word-matching to smart, semantic understanding using Large Language Models (LLMs) as judges.
The Problem with Old School Metrics
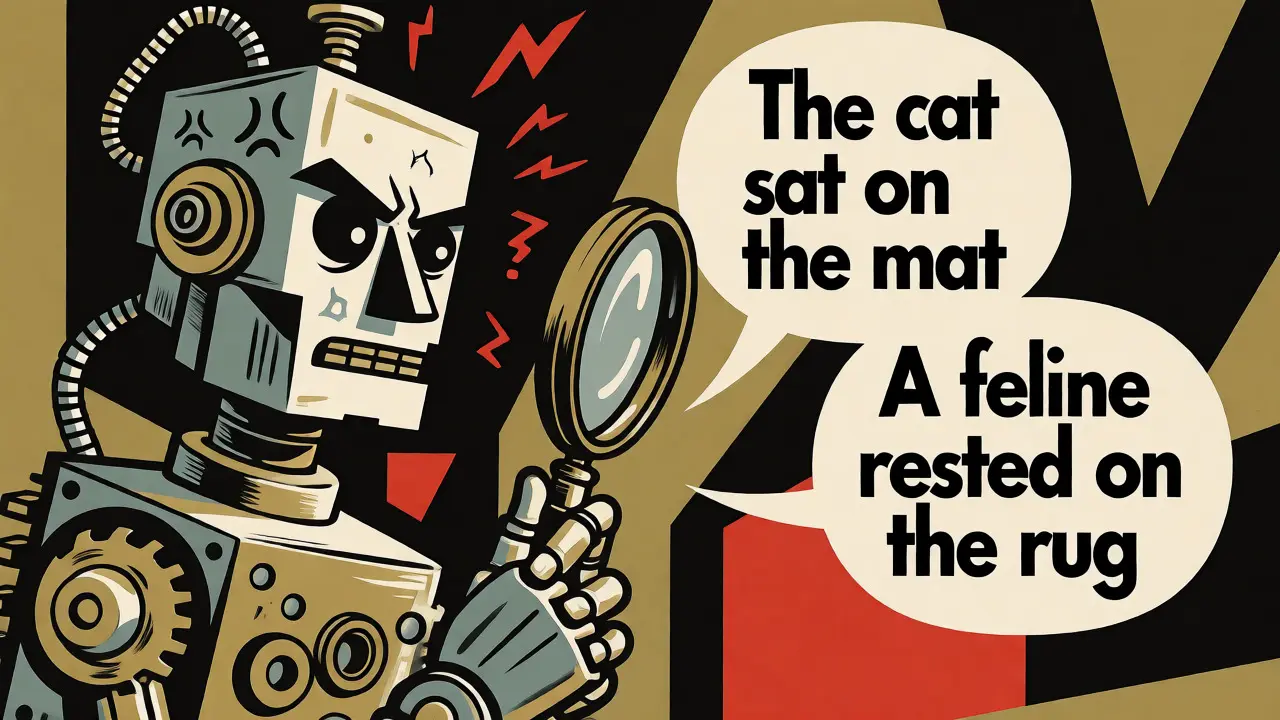
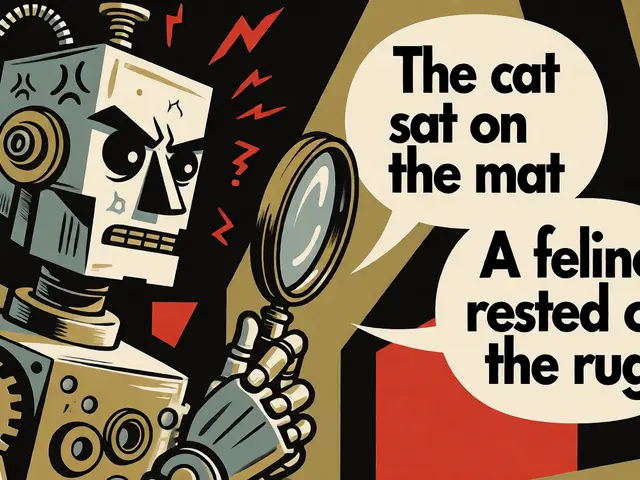
BLEU (Bilingual Evaluation Understudy) was created in 2002 for machine translation. The goal was simple: check if the translated sentence matched a human reference by counting shared words (n-grams). It was fast, cheap, and easy to code. But here is the catch: language isn't just about matching words. If I say "The cat sat on the mat" and you say "A feline rested on the rug," a human knows we mean the same thing. BLEU thinks you're wrong. It penalizes synonyms and paraphrasing heavily.
This creates a weird incentive. Developers started optimizing models to game the score rather than actually improve understanding. They would tweak outputs to use the specific vocabulary of the test set, even if it sounded robotic or unnatural. Research from Koehn back in 2004 showed that you could inflate BLEU scores by 15-20 points just by copying reference words, regardless of whether the meaning was accurate. We were effectively grading spelling tests when we should have been grading essays.
Enter the New Kids on the Block
To fix this, researchers developed metrics that understand context. BERTScore is one example. Instead of counting words, it looks at the meaning behind them using neural embeddings. If two sentences share similar concepts, BERTScore recognizes that connection even if the words differ. Another option is BLEURT, which is trained specifically to predict how humans feel about text quality. These tools bridge the gap between mechanical matching and human intuition.
But the biggest shift isn't just better math-it's using the AI itself to judge other AI. This is called LLM-as-a-Judge. You prompt a powerful model like GPT-4o to act as an evaluator. You give it a rubric-say, "Rate this answer for accuracy, clarity, and tone"-and let it decide. Recent studies show that LLM-as-a-Judge correlates with human opinions about 81.3% of the time. That's nearly as good as two humans agreeing with each other.
| Metric Type | Speed/Cost | Human Correlation | Best Use Case |
|---|---|---|---|
| Statistical (BLEU/ROUGE) | Instant / Free | Low (often misleading) | Quick regression checks, strict formatting tasks |
| Embedding-Based (BERTScore) | Fast / Low Cost | Medium-High | Semantic similarity, summarization |
| LLM-as-a-Judge | Slow / API Costs | Very High (~81%) | Nuanced reasoning, factuality, creative writing |
How LLM-as-a-Judge Actually Works
It’s not magic; it’s careful prompting. There are three main ways to do this:
- Pointwise Evaluation: The LLM assigns a numerical score (e.g., 1-10) to a single output based on criteria.
- Pairwise Comparison: You give the LLM two answers and ask, "Which one is better?" This often yields more consistent results because comparing two things is easier for a model than grading one in isolation.
- Pass/Fail: A binary judgment. Did the answer meet the safety guidelines? Yes or no.
A key finding from 2026 research is that the *quality of your instructions* matters more than which model you pick. Giving a smaller, cheaper model a clear, detailed rubric often beats giving a huge, expensive model vague instructions. Also, don't rely on a single run. LLMs can be slightly random. Run the evaluation multiple times and take the average to smooth out the noise.
When to Use What
You shouldn't throw away old metrics entirely. They still have a place. Think of it like a toolbox. You wouldn't use a sledgehammer to hang a picture frame, nor would you use a screwdriver to break concrete.
Use BLEU or ROUGE when you need speed. If you are running thousands of tests during development and just want to know if the model broke completely, these are fine. They are deterministic and free.
Use BERTScore when meaning matters more than exact wording. For summarization or translation where paraphrasing is expected, embedding-based metrics give a much fairer picture of performance.
Use LLM-as-a-Judge for high-stakes decisions. If you are launching a chatbot, checking for hallucinations, or evaluating customer support responses, you need the nuance that only an advanced model can provide. It catches subtle errors in logic or tone that statistical metrics miss completely.
The Hidden Costs and Pitfalls
Switching to LLM-as-a-Judge isn't free. First, there is money. Calling an API costs cents per request, which adds up quickly if you are evaluating millions of examples. Second, there is latency. Statistical metrics take milliseconds. An LLM call takes seconds. If you need real-time feedback in a production loop, this delay can be a problem.
There is also bias. If your judge model has blind spots, those will bleed into your evaluation. For instance, some models prefer longer answers over concise ones, even if the shorter answer is better. To mitigate this, always calibrate your LLM judge against a small set of human-rated examples. Check the correlation. If your LLM judge disagrees with humans on known cases, your rubric needs work.
Building a Modern Evaluation Pipeline
Don't rely on one number. Build a layered approach. Start with fast statistical checks to filter out obvious failures. Then, apply semantic metrics to assess general quality. Finally, reserve LLM-as-a-Judge for the final validation stage or for specific complex queries.
Platforms like Weights & Biases and Galileo AI now offer dashboards that automate this mix. They help you track cost versus accuracy trade-offs. The trend is moving toward task-specific metrics. Code generation is evaluated by execution success, not text similarity. RAG systems are judged by retrieval precision and grounding accuracy. One size no longer fits all.
Is BLEU completely obsolete?
No, but its role has shrunk. It is still useful for quick sanity checks and tasks requiring strict lexical overlap, like certain types of translation or keyword extraction. However, it should never be the sole metric for judging modern conversational AI or generative models.
Why does LLM-as-a-Judge correlate so well with humans?
Because LLMs are trained on vast amounts of human-written text. They learn patterns of style, coherence, and logic that mimic human intuition. Unlike n-gram counters, they understand context, semantics, and nuance, allowing them to evaluate text similarly to how a human editor would.
Does using a bigger model make a better judge?
Not necessarily. Research shows that the quality of the evaluation criteria (the rubric) and the reference answers impacts alignment more than the size of the judge model. A well-prompted mid-sized model often outperforms a poorly prompted giant model.
What is the main risk of using LLMs to evaluate LLMs?
Bias inheritance. If the judge model favors verbose answers or has specific cultural biases, it will reward those traits in the candidate model. Always validate your LLM judge against human annotations to ensure it isn't rewarding bad habits.
How much does LLM-as-a-Judge cost compared to BLEU?
BLEU is essentially free and instant. LLM-as-a-Judge involves API costs (typically $0.01-$0.10 per evaluation depending on length) and significant latency (seconds vs. milliseconds). For large-scale datasets, this cost can become substantial, so it's best used selectively.

its all rigged anyway
the big tech labs want us to believe their own models are the gold standard so they can charge us for the api calls while we pay them to grade our homework
who watches the watchers exactly
we are just feeding data into a black box that spits out numbers and we nod along like good little sheep because we are too lazy to read the actual text ourselves
i bet the bias is baked in deeper than anyone admits