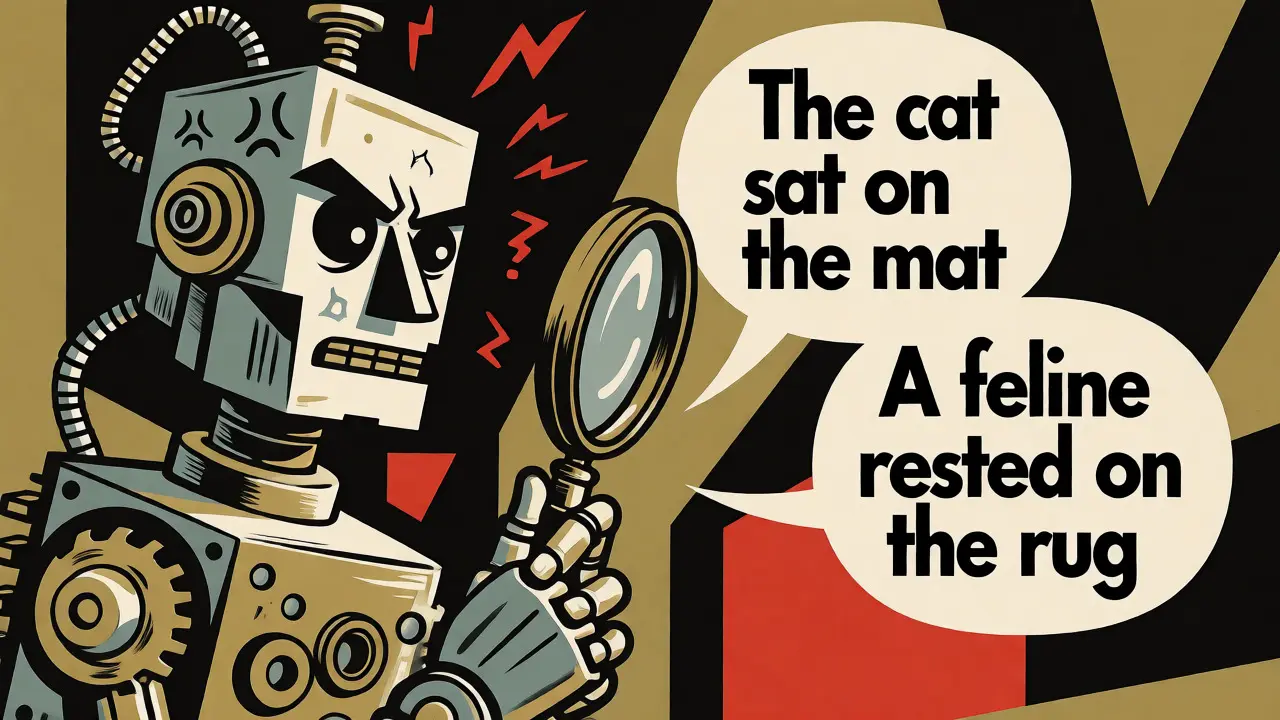
NLP Evaluation: Why BLEU Fails and LLM-as-a-Judge Wins
Discover why NLP evaluation is shifting from rigid BLEU scores to smarter LLM-as-a-Judge metrics. Learn how to balance speed, cost, and accuracy in your AI workflows.
Building Custom LLM Benchmarks for Enterprise Success
Discover why generic LLM benchmarks fail in enterprise settings and learn how to build custom evaluation frameworks. This guide covers data construction, LLM-as-a-Judge scoring, and RAG integration to ensure your AI solves real business problems.
LLM-as-a-Judge: How to Use AI Models to Evaluate Other LLMs
Discover how LLM-as-a-Judge methods use advanced models to evaluate other LLMs. Learn implementation strategies, key metrics like faithfulness and hallucination detection, and how to balance automated scoring with human oversight.