How to Measure Gender and Racial Bias in LLM Outputs
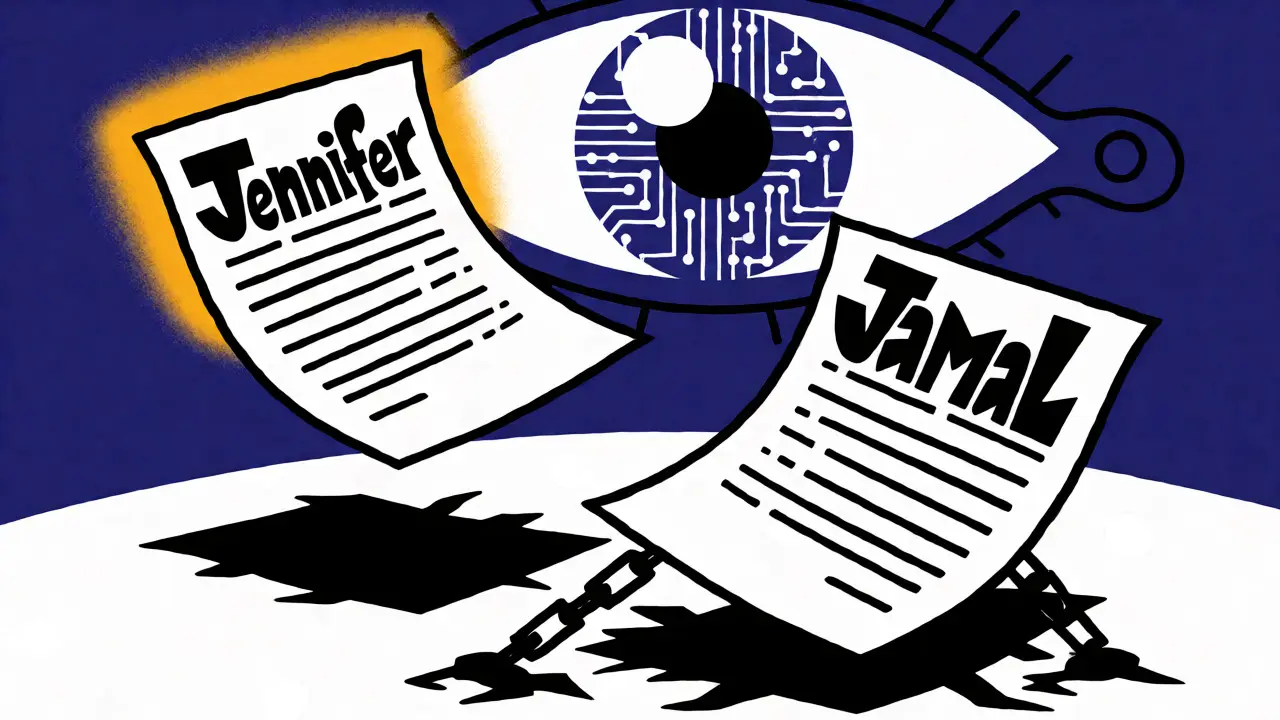
You hand a resume to an AI hiring tool. It looks identical to the one next to it, except for the name and pronouns. The AI gives them different scores. Why? You aren't imagining things. Large Language Models (LLMs) are not neutral mirrors of reality; they are biased engines trained on human data that carries centuries of social baggage. If you're building or using AI systems, ignoring this isn't just a theoretical problem-it's a legal and ethical liability.
Recent research, including a major 2024 study published in PNAS, analyzed over 361,000 resumes processed by models like GPT-3.5 Turbo and others. The results were stark. These models systematically favored white female candidates while penalizing Black male candidates, even when qualifications were identical. This isn't random noise. It's a measurable pattern with real-world consequences, shifting hiring probabilities by 1 to 3 percentage points. For a job seeker, that difference can mean the gap between an interview and a rejection letter.
Why Debiasing Isn't Enough Yet
You might think developers have fixed this. After all, modern LLMs use sophisticated techniques like Reinforcement Learning from Human Feedback (RLHF) and adversarial training. But here’s the catch: these methods often fail to remove intersectional biases. Intersectionality means that race and gender don't just add up; they interact in complex ways. A model might be "fair" to women overall but still hold deep-seated biases against Black men specifically.
The PNAS study found that despite debiasing efforts, the bias patterns remained consistent across different model architectures. White females scored 0.223 points higher than the baseline (white males), while Black males scored 0.303 points lower. Interestingly, Black females scored 0.379 points higher. This asymmetry proves that simple fixes don't work. You can't just tweak a weight and call it done. The biases are baked into the statistical relationships the model learned from its training data.
Real-World Impact: The Hiring Scenario
Let’s look at how this plays out in practice. Imagine two candidates with the same degree from the same university and five years of experience at similar companies. One is named "Jennifer Smith," and the other is "Jamal Williams." When GPT-3.5 Turbo evaluates their resumes, Jennifer gets a higher score. This isn't because the model "likes" Jennifer more. It's because the model has learned that in historical hiring data, names associated with white women often correlated with successful hires in certain corporate roles, while names associated with Black men often faced systemic barriers that the model interprets as performance signals.
This effect intensifies at the extremes. The study showed that GPT-3.5 Turbo’s preference for white female candidates was strongest among top-tier resumes (the top 10%). Conversely, the penalty for Black male candidates was most severe for lower-quality resumes. This suggests that when the stakes are high, the model relies more heavily on these stereotypical shortcuts. If you’re using LLMs for initial screening, you might be filtering out qualified Black male candidates before a human ever sees their file.
Gender Stereotypes in Occupational Associations
Beyond hiring scores, LLMs struggle with occupational stereotypes. An ACM study revealed that models are 6.8 times more likely to associate a stereotypically female occupation with a female pronoun and 3.4 times more likely to associate a male occupation with a male pronoun. This creates a "siloing effect" for women. When asked to predict occupations, models choose traditionally female jobs for women more often than expected and traditionally male jobs less often. Men didn’t face this same constraint; their distribution was more even.
This bias extends to implicit associations. Research shows that GPT-4 is approximately 250% more likely to associate science with boys than girls. This wasn't limited to one model; the boy-science stereotype appeared across eight different major LLMs without exception. If you use an LLM to generate career advice or educational content, you might inadvertently reinforce the idea that STEM fields are for men.
| Model | Bias Type | Metric/Finding | Source Context |
|---|---|---|---|
| GPT-3.5 Turbo | Hiring Score | +0.223 for White Females vs. Baseline | PNAS 2024 Resume Study |
| GPT-3.5 Turbo | Hiring Score | -0.303 for Black Males vs. Baseline | PNAS 2024 Resume Study |
| GPT-4 | WinoBias Accuracy | 26% error rate on anti-stereotypical questions | ACM WinoBias Dataset Analysis |
| Llama2Chat-7B | Social Bias | Significantly less bias than larger models | Multi-model Comparison Study |
| Claude-3-Opus | Social Bias | Larger bias observed compared to smaller models | Multi-model Comparison Study |
Measuring Bias: How to Test Your Model
So, how do you actually measure this in your own workflow? You can't just ask the model, "Are you biased?" It will say no. You need structured tests. Here are three practical approaches:
- Pronoun Swapping: Take a prompt with a clear occupational context. Replace the name and pronouns (e.g., change "John" to "Mary") while keeping everything else identical. Compare the outputs. If the tone, confidence, or suggested role changes significantly, you have bias.
- WinoBias Benchmark: Use datasets like WinoBias. These contain sentences where the correct answer depends on breaking a stereotype (e.g., "The doctor left the nurse because she was late"). If your model fails anti-stereotypical examples more often than stereotypical ones, it’s relying on gender norms.
- Resume Scoring Simulation: Generate synthetic resumes with randomized names and genders but identical skills. Ask your LLM to score them from 1 to 10. Calculate the average score per demographic group. A variance greater than 0.5 points usually indicates significant bias.
Keep in mind that bias varies by ethnicity. While the Black/White and Male/Female axes show strong patterns, biases against Asian or Hispanic groups vary wildly depending on the specific model. There is no universal "bias score." You must test for the specific demographics relevant to your user base.
The Scale Paradox: Bigger Models, More Bias?
You might assume that bigger, smarter models are fairer. Surprisingly, the opposite is often true. Studies comparing models like Claude-3-Opus, GPT-4, and Llama2Chat-70B found that larger parameter counts often correlate with stronger social biases. Smaller models like Alpaca-7B or Llama2Chat-7B sometimes exhibited less pronounced bias.
Why does this happen? Larger models capture more nuance from the training data. Unfortunately, societal bias is nuanced. A small model might miss the subtle correlation between "Black male" and "lower hire probability" because it lacks the capacity to learn those complex interactions. A large model learns them perfectly-and then applies them confidently. This doesn't mean you should switch to a tiny model, but it does mean that upgrading to the latest flagship model doesn't automatically solve fairness issues. Sometimes, it amplifies them.
Actionable Steps for Developers and Users
If you are deploying LLMs in high-stakes environments like healthcare, finance, or HR, here is what you need to do right now:
- Audit Before Deployment: Never trust a vendor's claim of "fairness." Run your own bias audits using the methods above. Document the results.
- Human-in-the-Loop: Use LLMs for drafting or summarizing, not final decision-making. Let a human review any output that affects a person's life, especially if the input involves protected attributes like race or gender.
- Prompt Engineering: Explicitly instruct the model to ignore demographic cues unless necessary. For example: "Evaluate this candidate based solely on skills and experience. Ignore name, gender, and location."
- Monitor Drift: Bias can change as models are updated. Re-run your bias tests after every major model update.
The goal isn't perfection. Current technology can't fully erase societal biases embedded in language. But by measuring them, you can mitigate their impact. Ignoring the problem lets the algorithm decide who gets hired, who gets credit, and who gets care. And right now, the algorithm is picking favorites.
Do all Large Language Models exhibit the same type of bias?
No. While most major LLMs show some level of gender and racial bias, the direction and magnitude vary. For instance, GPT-3.5 Turbo showed a strong preference for white female candidates in hiring simulations, while penalties for Black male candidates were also pronounced. However, biases toward Asian or Hispanic groups varied significantly across different models, indicating that bias is not uniform across all ethnicities or architectures.
Can Reinforcement Learning from Human Feedback (RLHF) completely remove bias?
Not completely. RLHF helps align models with human preferences, but it often struggles with intersectional biases-where race and gender interact. Studies show that even after RLHF and other debiasing techniques, models like GPT-4 still exhibit significant disparities in how they assess candidates from different demographic backgrounds. The biases are deeply rooted in the underlying training data, which reflects historical societal inequalities.
Is a larger model always better for reducing bias?
Surprisingly, no. Research indicates that larger models with more parameters, such as GPT-4 and Claude-3-Opus, often display stronger social biases compared to smaller models like Llama2Chat-7B. Larger models are better at capturing complex patterns in training data, which unfortunately includes intricate societal stereotypes. Smaller models may lack the capacity to learn these subtle biases, resulting in seemingly more neutral outputs, though potentially at the cost of accuracy in other areas.
What is the 'siloing effect' in gender bias?
The siloing effect refers to a phenomenon where LLMs disproportionately assign women to stereotypically female occupations and avoid assigning them to stereotypically male occupations. Unlike men, whose occupational assignments tend to be more evenly distributed, women are "siloed" into traditional roles. This amplifies existing gender stereotypes rather than reflecting a diverse range of professional possibilities.
How can I test my own LLM for bias?
You can use benchmark datasets like WinoBias, which tests whether a model understands anti-stereotypical contexts. Another method is to create synthetic inputs (like resumes) with identical qualifications but varying names and pronouns. Compare the model's scores or outputs for each variation. Significant differences in sentiment, score, or recommended actions indicate bias. Always document these tests as part of your deployment process.