Education Hub for Generative AI

Tag: AI speedup

Speculative Decoding for Large Language Models: How Draft and Verifier Models Speed Up AI Responses 3 August 2025

Speculative Decoding for Large Language Models: How Draft and Verifier Models Speed Up AI Responses

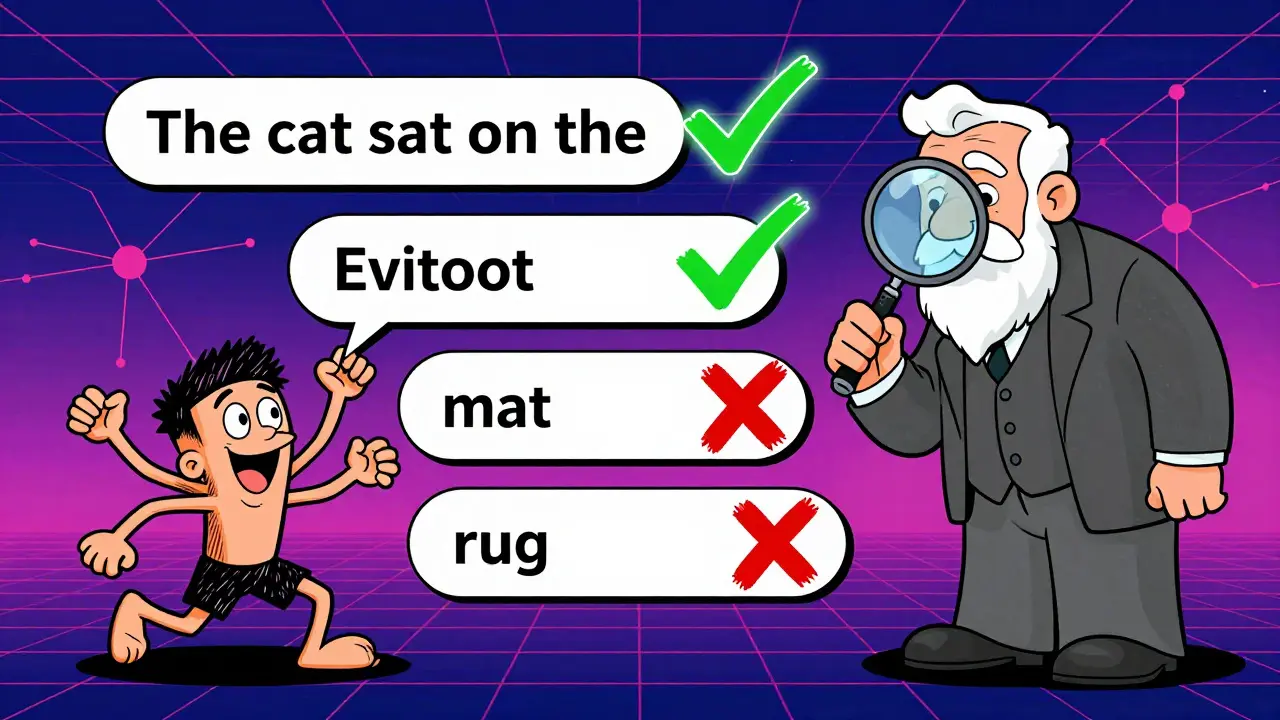
Speculative decoding accelerates large language models by pairing a fast draft model with a verifier model, cutting response times by up to 5x without losing quality. Used by AWS, Google, and Meta, it's now standard in enterprise AI.
Susannah Greenwood 7 Comments

About

AI & Machine Learning

Latest Stories

Security Basics for Non-Technical Builders Using Vibe Coding Platforms

Security Basics for Non-Technical Builders Using Vibe Coding Platforms

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

API LLMs vs On-Prem Deployment: Latency and Control Tradeoffs

API LLMs vs On-Prem Deployment: Latency and Control Tradeoffs

Marketing Vibe Coding Wins Internally: A Guide to Internal Adoption

Marketing Vibe Coding Wins Internally: A Guide to Internal Adoption

Hot vs. Cold Start Optimization for LLM Containers: A Practical Guide

Hot vs. Cold Start Optimization for LLM Containers: A Practical Guide

Shadow Prompting and Data Exfiltration Risks in LLM Workflows

Shadow Prompting and Data Exfiltration Risks in LLM Workflows

Education Hub for Generative AI
© 2026. All rights reserved.