Education Hub for Generative AI

Tag: VATT model

Multimodal Transformer Foundations: How Text, Image, Audio, and Video Embeddings Are Aligned 30 November 2025

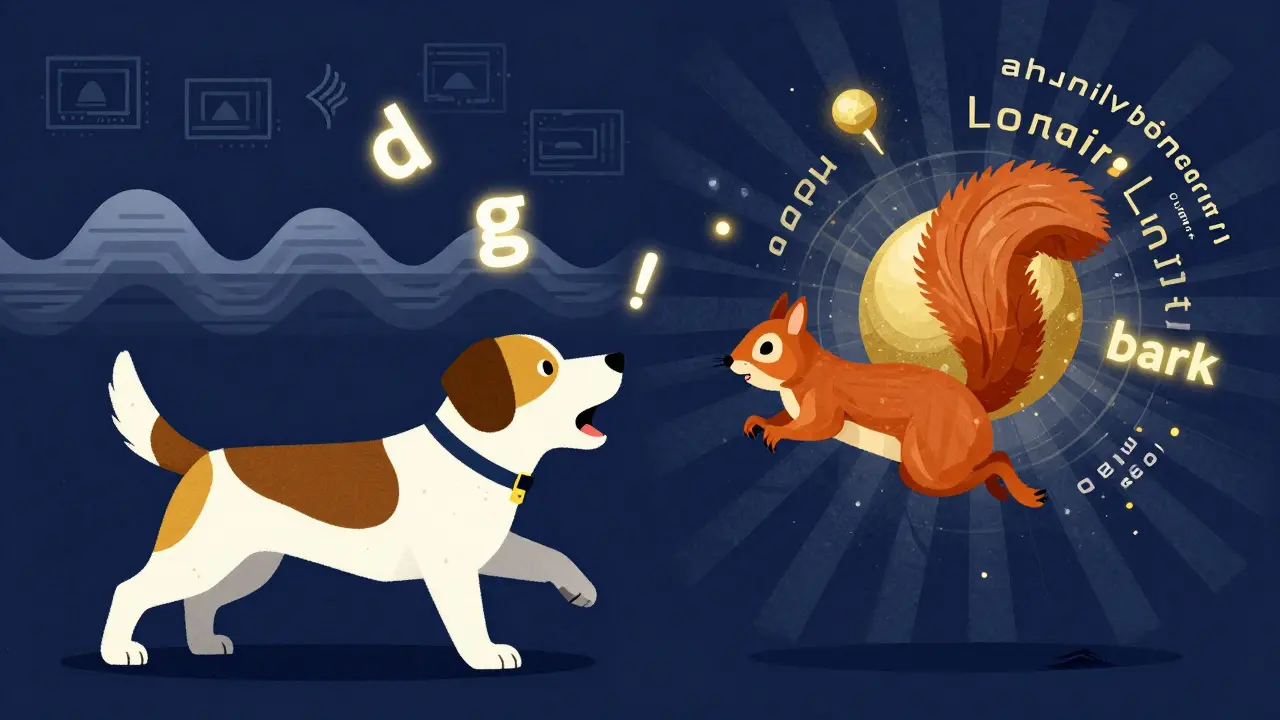
Multimodal Transformer Foundations: How Text, Image, Audio, and Video Embeddings Are Aligned

Multimodal transformers align text, image, audio, and video into a shared embedding space, enabling systems to understand the world like humans do. Learn how they work, where they're used, and why audio remains the hardest modality to master.
Susannah Greenwood 7 Comments

About

AI & Machine Learning

Latest Stories

Agentic Generative AI: How Autonomous Agents Execute Multi-Step Workflows

Agentic Generative AI: How Autonomous Agents Execute Multi-Step Workflows

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

API LLMs vs On-Prem Deployment: Latency and Control Tradeoffs

API LLMs vs On-Prem Deployment: Latency and Control Tradeoffs

Keeping RAG Systems Fresh: Document Sync Strategies for LLMs

Keeping RAG Systems Fresh: Document Sync Strategies for LLMs

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Maximizing Talent Strategy ROI for Generative AI: Upskilling vs. Recruitment

Maximizing Talent Strategy ROI for Generative AI: Upskilling vs. Recruitment

Hot vs. Cold Start Optimization for LLM Containers: A Practical Guide

Hot vs. Cold Start Optimization for LLM Containers: A Practical Guide

Education Hub for Generative AI
© 2026. All rights reserved.