PII Detection and Redaction Pipelines for LLM Inputs and Outputs
You just pasted a customer support ticket into your LLM chatbot. It contains an email address, a phone number, and maybe a credit card fragment. You hit send. Did that sensitive data go straight to the model provider? Was it logged in your server traces? Did it get baked into a future training set?
If you aren't running a PII detection and redaction pipeline, the answer is probably yes. And that’s a problem. Not just because of GDPR fines or CCPA lawsuits, but because leaking user data erodes trust faster than any bug fix can restore it.
Building a robust privacy layer isn't about slapping a regex on your input field and calling it a day. It’s about designing a pipeline that catches structured data like emails, understands context to spot names hidden in sentences, and scrubs outputs before they reach the user. This guide breaks down how to build that pipeline using current best practices, tools like Microsoft Presidio, and hybrid detection strategies that actually work in production.
Why Regex Alone Fails in LLM Contexts
Most developers start with Regular Expressions (Regex). They’re fast, cheap, and great at finding things with strict formats: email addresses, phone numbers, US Social Security Numbers, and credit card digits. If you have a string like "my email is [email protected]", a simple regex pattern will catch "[email protected]" every time.
But LLM inputs are messy. People don't speak in JSON schemas. They write things like "Call me at my office, 555-0199, or text my cell." A basic regex might miss which number is personal and which is business. Worse, it completely fails on unstructured entities like names, addresses, or medical conditions unless you have massive, brittle dictionaries.
In one production study, regex-only baselines achieved only 65% recall. That means 35% of PII slipped through undetected. For a healthcare app handling HIPAA data, that’s unacceptable. You need Named Entity Recognition (NER) models to understand context. NER looks at the words surrounding a potential entity to determine if "John" is a person's name or a common noun. This contextual awareness pushes recall rates above 96%, drastically reducing leakage risk.
The Hybrid Architecture: Speed Meets Accuracy
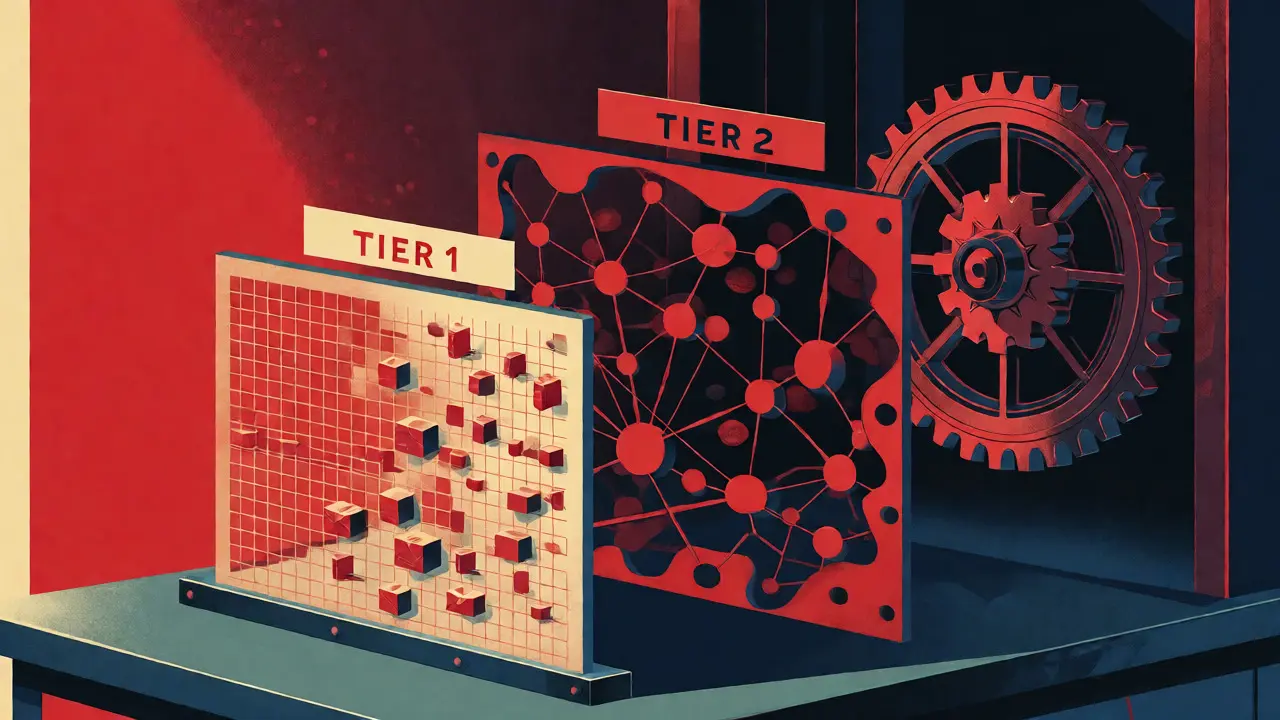
So, should you ditch Regex? No. The smartest pipelines use a tiered approach. Think of it as a security checkpoint with multiple layers.
- Tier 1: Fast-Pass Filter (Regex). Scan for high-confidence, structured patterns first. Emails, IPs, and SSNs are easy wins. If found, mask them immediately. This step is incredibly fast and requires minimal compute.
- Tier 2: Contextual Analysis (NER). Pass the remaining text through a lightweight NER model. Tools like spaCy or Microsoft Presidio analyze sentence structure to identify names, locations, and organizations. This is slower but catches what Regex misses.
- Tier 3: Validation & Checksums. Before masking, validate detected entities. Is that 16-digit number actually a valid credit card? Use Luhn algorithm checks. Does that ZIP code match the city mentioned earlier? Cross-reference to reduce false positives.
This hybrid method balances latency and accuracy. You avoid running expensive NER models on text that Regex already cleared, saving milliseconds per request-critical when you're processing thousands of prompts per minute.
Implementing with Microsoft Presidio and Python Microservices
Microsoft Presidio has become the de facto standard for open-source PII detection. It’s not just a library; it’s a framework that lets you define custom recognizers, anonymizers, and analyzers. Here’s how teams typically deploy it.
Rather than embedding heavy NLP libraries directly into your main application logic, decouple them. Use a Go-based processor to intercept telemetry and application traces. This component extracts the target attributes (like `llm.prompt`) and sends them via gRPC to a dedicated Python microservice running Presidio.
| Method | Recall Rate | Latency | Best For |
|---|---|---|---|
| Regex Only | ~65% | < 1ms | Structured IDs, Emails |
| Presidio (Hybrid) | > 96% | 50-200ms | General Purpose, Production Apps |
| Fine-tuned LLM | > 98% | 500ms+ | Complex Context, Low Volume |
The Python service handles the heavy lifting: loading the NER models, applying Presidio’s pattern library, and returning masked text. This separation allows you to scale the detection service independently from your API gateway. If traffic spikes, you spin up more Python containers without touching your core application code.
Handling Input Sanitization vs. Output Restoration
Detection isn’t just about hiding data from the LLM provider. It’s also about ensuring the final answer makes sense to the user. If you replace every instance of "John Smith" with "
Advanced pipelines implement placeholder replacement. When you detect PII in the input, you store the original value in a temporary cache keyed by a unique ID (e.g., `
This ensures the LLM never sees the real name, but the user gets a natural conversation. Just be careful: if the LLM hallucinates a new name or ignores the placeholder, your restoration logic needs fallbacks. Always validate that the output structure matches expectations before swapping values back in.
Cloud-Native Integrations: AWS and Azure
If you’re already deep in cloud ecosystems, you might not want to manage custom microservices. Both AWS and Azure offer native PII detection features that integrate with their data pipelines.
Amazon SageMaker Data Wrangler integrates Amazon Comprehend to automatically redact PII during machine learning data preparation. This is ideal for batch processing large datasets before training models. However, it’s less suited for real-time inference where you need sub-second latency.
Microsoft Fabric provides AI functions like `ai.extract` and `ai.generate_response` that allow PII identification directly within data pipeline operations. While convenient, these services often have rate limits (e.g., 1,000 requests per minute) and may lack the granular control of self-hosted Presidio instances. For high-volume applications, self-managed solutions usually offer better cost-performance ratios.
Regulatory Drivers: GDPR, CCPA, and HIPAA
Why invest in this infrastructure now? Because regulators are watching. GDPR mandates data minimization-collect only what you need. Sending raw user data to third-party LLM providers violates this principle if that data includes unnecessary PII. CCPA gives consumers the right to know what data is collected and sold. If your logs contain unredacted emails, you’re exposing yourself to liability.
HIPAA is even stricter for healthcare. Protected Health Information (PHI) must be secured end-to-end. A single leaked patient record in an LLM trace can trigger significant penalties. By implementing redaction pipelines, you demonstrate "reasonable security measures," a key defense in regulatory audits.
Testing Your Pipeline: Synthetic Data and Edge Cases
How do you know your redactor works? Don’t rely on manual testing alone. Use synthetic data generators like the NLU-Redact-PII GitHub repository to create diverse test cases. Generate thousands of variations: typos, mixed languages, slang, and fragmented sentences.
Measure three metrics:
- Redaction Accuracy: Did we catch the PII?
- Semantic Preservation: Did we accidentally delete non-sensitive words that changed the meaning?
- Leakage Rate: How much PII escaped detection?
Aim for near-zero leakage. Even a 1% failure rate is dangerous when processing millions of records. Run regression tests whenever you update your NER models or add new Regex patterns to ensure changes don’t break existing protections.
Common Pitfalls to Avoid
Teams often stumble on a few predictable issues. First, ignoring multilingual support. Most default NER models are optimized for English. If your users speak Spanish or German, detection accuracy drops significantly. Test explicitly for your target languages or fine-tune models accordingly.
Second, forgetting about indirect identifiers. A combination of "male," "born in 1975," and "lives in Asheville" might uniquely identify someone, even if no single field is PII. Advanced systems look for quasi-identifiers, though this adds complexity.
Third, neglecting output scanning. Developers focus heavily on sanitizing inputs but forget that LLMs can regurgitate PII from their training data or echo it back in responses. Always run your redaction pipeline on both directions: inbound prompts and outbound completions.
Frequently Asked Questions
Does redacting PII affect the quality of LLM responses?
It can, but minimally if done correctly. Replacing specific entities with generic placeholders (like
Is Microsoft Presidio free to use in commercial products?
Yes, Microsoft Presidio is open-source software released under the MIT License. This means you can use it in commercial products, modify the code, and distribute it without paying licensing fees. However, you are responsible for hosting the infrastructure and maintaining the dependencies, unlike managed cloud services which charge for usage.
How does PII redaction impact latency in real-time applications?
Detection adds overhead, typically 50-200 milliseconds depending on the model size and hardware. For most chat interfaces, this is imperceptible to users. However, for high-frequency trading bots or real-time voice assistants, this delay matters. To mitigate this, use asynchronous processing, cache results for repeated patterns, and employ lighter-weight NER models for initial screening.
Can LLMs themselves be used to detect PII?
Yes, fine-tuned smaller language models can perform PII detection with high accuracy. These models understand context better than traditional NER systems. However, they are computationally expensive and introduce higher latency compared to rule-based or lightweight ML approaches. They are best reserved for complex edge cases or low-volume, high-sensitivity tasks rather than bulk processing.
What happens if the LLM hallucinates PII in its output?
If the LLM generates fake names or addresses that weren't in the input, your redaction pipeline should still catch them if they match known PII patterns (like valid-looking emails or phone numbers). However, detecting hallucinated entities that don't fit standard formats is difficult. Running the output through the same detection pipeline as the input ensures consistency, catching both echoed and newly generated sensitive data.