Education Hub for Generative AI

Tag: draft model

Speculative Decoding for Large Language Models: How Draft and Verifier Models Speed Up AI Responses 3 August 2025

Speculative Decoding for Large Language Models: How Draft and Verifier Models Speed Up AI Responses

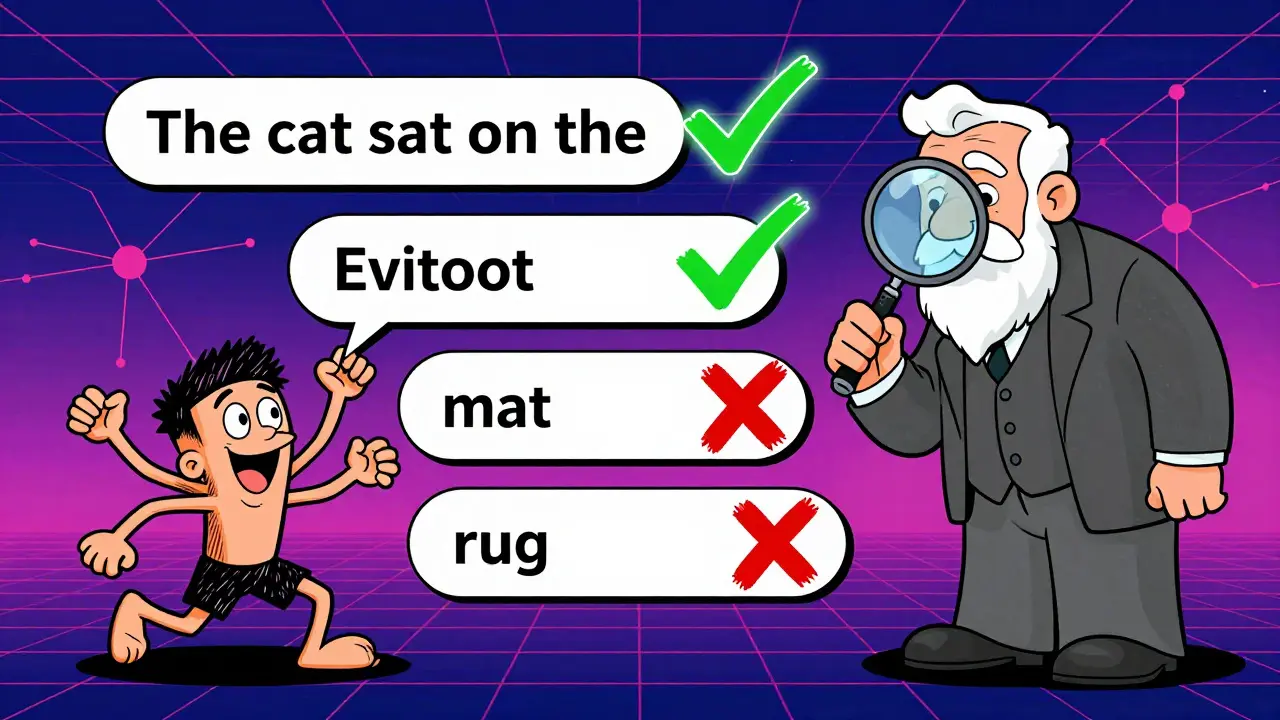
Speculative decoding accelerates large language models by pairing a fast draft model with a verifier model, cutting response times by up to 5x without losing quality. Used by AWS, Google, and Meta, it's now standard in enterprise AI.
Susannah Greenwood 7 Comments

About

AI & Machine Learning

Latest Stories

Vibe Coding Retrospectives: How to Fix AI Code Failures

Vibe Coding Retrospectives: How to Fix AI Code Failures

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

Children's Data and Vibe Coding: COPPA and Age Gates Explained

Children's Data and Vibe Coding: COPPA and Age Gates Explained

Consent Management in Generative AI: User Rights and Data Choices

Consent Management in Generative AI: User Rights and Data Choices

Governance KPIs That Matter: Policy Adherence, Review Coverage, and MTTR

Governance KPIs That Matter: Policy Adherence, Review Coverage, and MTTR

Logging and Observability for Production LLM Agents: A Practical Guide

Logging and Observability for Production LLM Agents: A Practical Guide

Refactoring Sprints for Vibe-Coded Apps: A Guide to Scope and Schedule

Refactoring Sprints for Vibe-Coded Apps: A Guide to Scope and Schedule

Education Hub for Generative AI
© 2026. All rights reserved.