Education Hub for Generative AI

Tag: LLM defenses

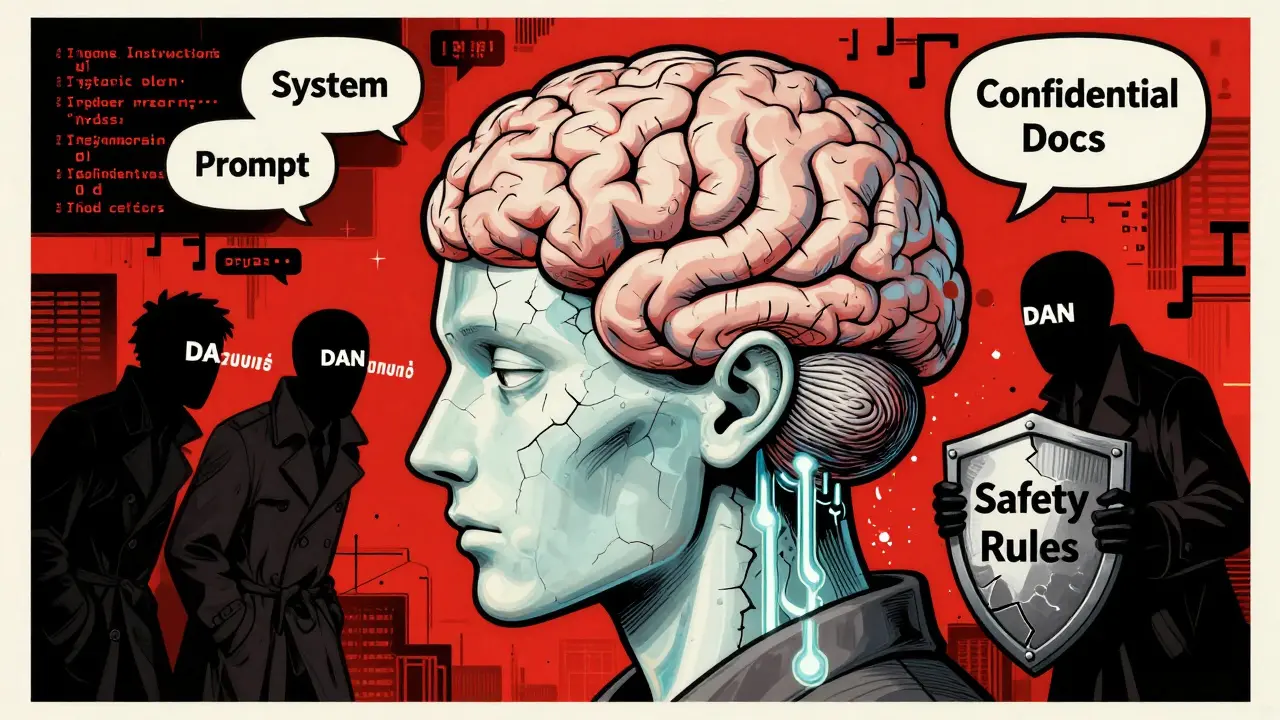
Prompt Injection Risks in Large Language Models: How Attacks Work and How to Stop Them 31 August 2025

Prompt Injection Risks in Large Language Models: How Attacks Work and How to Stop Them

Prompt injection attacks trick AI models into ignoring their rules, exposing sensitive data and enabling code execution. Learn how these attacks work, which systems are at risk, and what defenses actually work in 2025.
Susannah Greenwood 7 Comments

About

AI & Machine Learning

Latest Stories

Governance KPIs That Matter: Policy Adherence, Review Coverage, and MTTR

Governance KPIs That Matter: Policy Adherence, Review Coverage, and MTTR

Categories

  • AI & Machine Learning
  • Cloud Architecture & DevOps

Featured Posts

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Copyright Risks in Multimodal Generative AI: Images, Music, and Video

Evaluation Datasets for LLM Agent Benchmarks: A Practical Guide

Evaluation Datasets for LLM Agent Benchmarks: A Practical Guide

Hot vs. Cold Start Optimization for LLM Containers: A Practical Guide

Hot vs. Cold Start Optimization for LLM Containers: A Practical Guide

How to Measure Gender and Racial Bias in LLM Outputs

How to Measure Gender and Racial Bias in LLM Outputs

NLP Evaluation: Why BLEU Fails and LLM-as-a-Judge Wins

NLP Evaluation: Why BLEU Fails and LLM-as-a-Judge Wins

Education Hub for Generative AI
© 2026. All rights reserved.