Stochastic Depth and Regularization in Deep Transformer LLMs: A Practical Guide
Learn how stochastic depth improves deep transformer LLMs by reducing overfitting and boosting efficiency. Discover practical tips for drop schedules and combining it with other regularization techniques.
Production Guardrails for Compressed LLMs: Confidence and Abstention
Learn how production guardrails for compressed LLMs use confidence scores and abstention to balance safety and speed. Explore Defensive M2S, efficiency techniques, and implementation strategies.
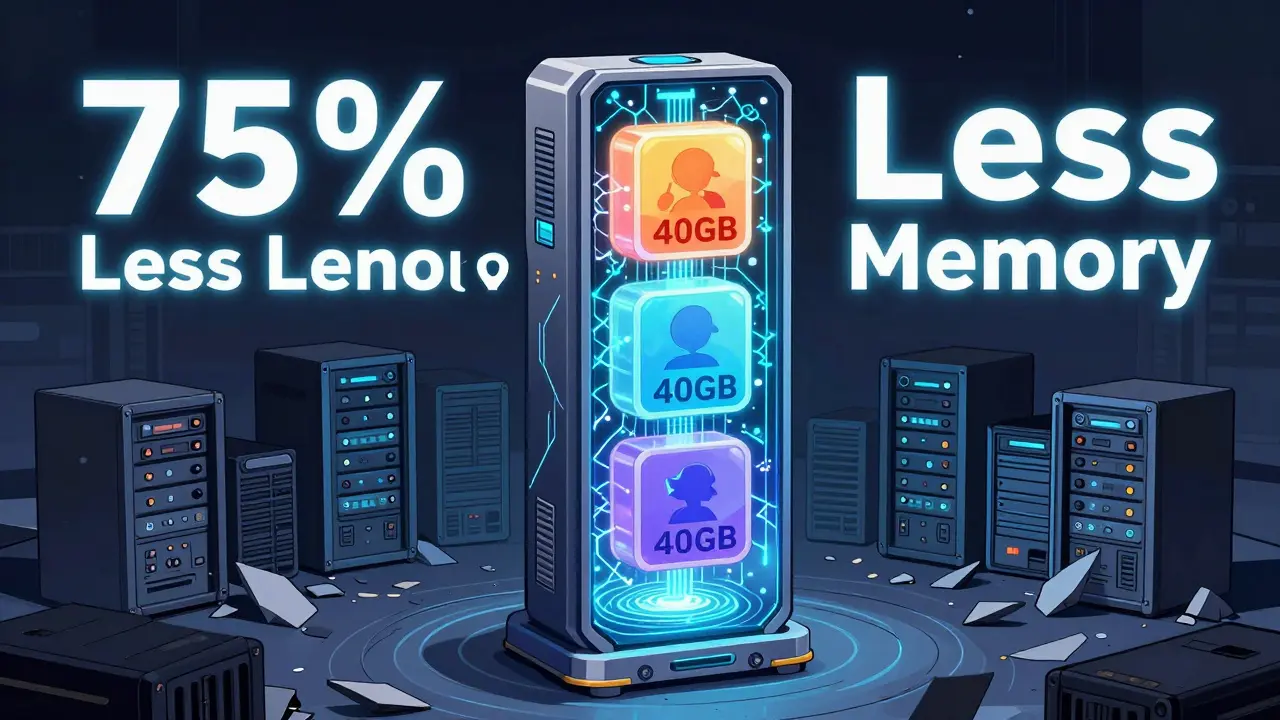
How to Reduce Memory Footprint for Hosting Multiple Large Language Models
Learn how to reduce memory footprint for hosting multiple large language models using quantization, model parallelism, and hybrid techniques. Cut costs, run more models on less hardware, and avoid common pitfalls.