LLM-as-a-Judge: How to Use AI Models to Evaluate Other LLMs
Discover how LLM-as-a-Judge methods use advanced models to evaluate other LLMs. Learn implementation strategies, key metrics like faithfulness and hallucination detection, and how to balance automated scoring with human oversight.
Task-Specific Scorecards: Evaluating LLM Summarization, Q&A, and Extraction
Learn how to build effective task-specific scorecards for LLMs. Discover metrics for summarization, Q&A, and extraction beyond basic ROUGE.
Truthfulness Benchmarks for Generative AI: Evaluating Factual Accuracy
Discover how truthfulness benchmarks like TruthfulQA evaluate generative AI's factual accuracy. Learn why bigger models aren't always more truthful and how to mitigate hallucination risks in enterprise applications.
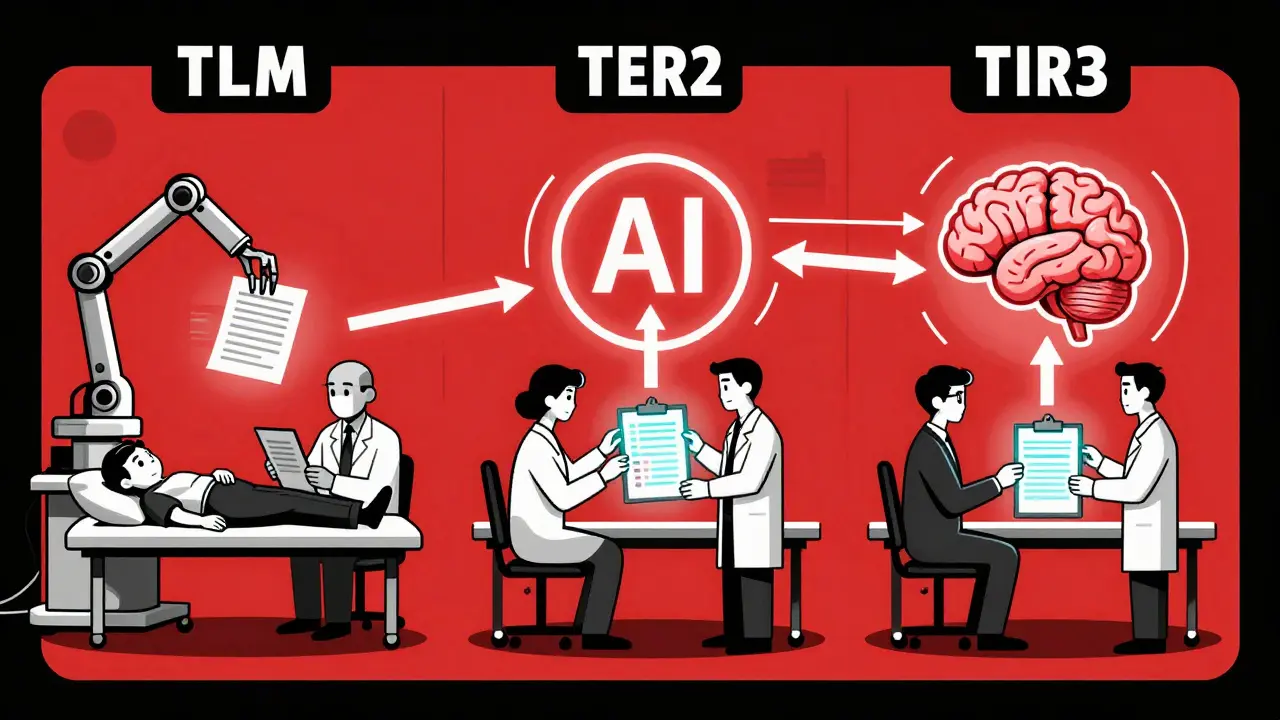
Human-in-the-Loop Evaluation Pipelines for Large Language Models
Human-in-the-loop evaluation pipelines combine AI speed with human judgment to ensure large language models produce accurate, safe, and fair outputs. Learn how tiered systems cut review time while improving quality.
Best Visualization Techniques for Evaluating Large Language Models
Discover the most effective visualization techniques for evaluating large language models, from bar charts and scatter plots to heatmaps and parallel coordinates - and learn how to avoid common pitfalls in model assessment.